
Key Metric
What changes when citation monitoring becomes citation alerting
Dashboards tell you what already drifted, weeks late. Alerting tells you the day it moved — these are the design constants of the pipeline in this guide.
Why Agentic Citation Alerts Matter
Buyers have moved a chunk of their research from search boxes to chat windows. When someone asks ChatGPT or Perplexity for a shortlist, the brands named in that answer get the click, the trust and the deal — and the brands left out do not even get a rejection email. That makes the citation the new ranking, and it happens with no rank-tracking tool watching it.
Here is the uncomfortable part: none of the major engines ships a dashboard that tells you which answers cite your brand. Google documents how AI features select and label sources, and Search Console has started separating AI-driven traffic, but neither gives you a per-brand citation feed (see Google’s AI features documentation). By the time a human notices you vanished from a money answer, the shift has been shaping buyer decisions for weeks.
Monthly reporting cannot fix this; the feedback loop is too slow. If you are new to the concept, our primer on autonomous citation engineering covers the strategy layer — and our AEO and GEO optimization service covers the done-for-you version. Agentic citation alerts are the nervous system underneath: an agent pipeline that watches your citation footprint continuously and pings you only when something actually changes.
How the Agentic Citation Alerts Pipeline Works
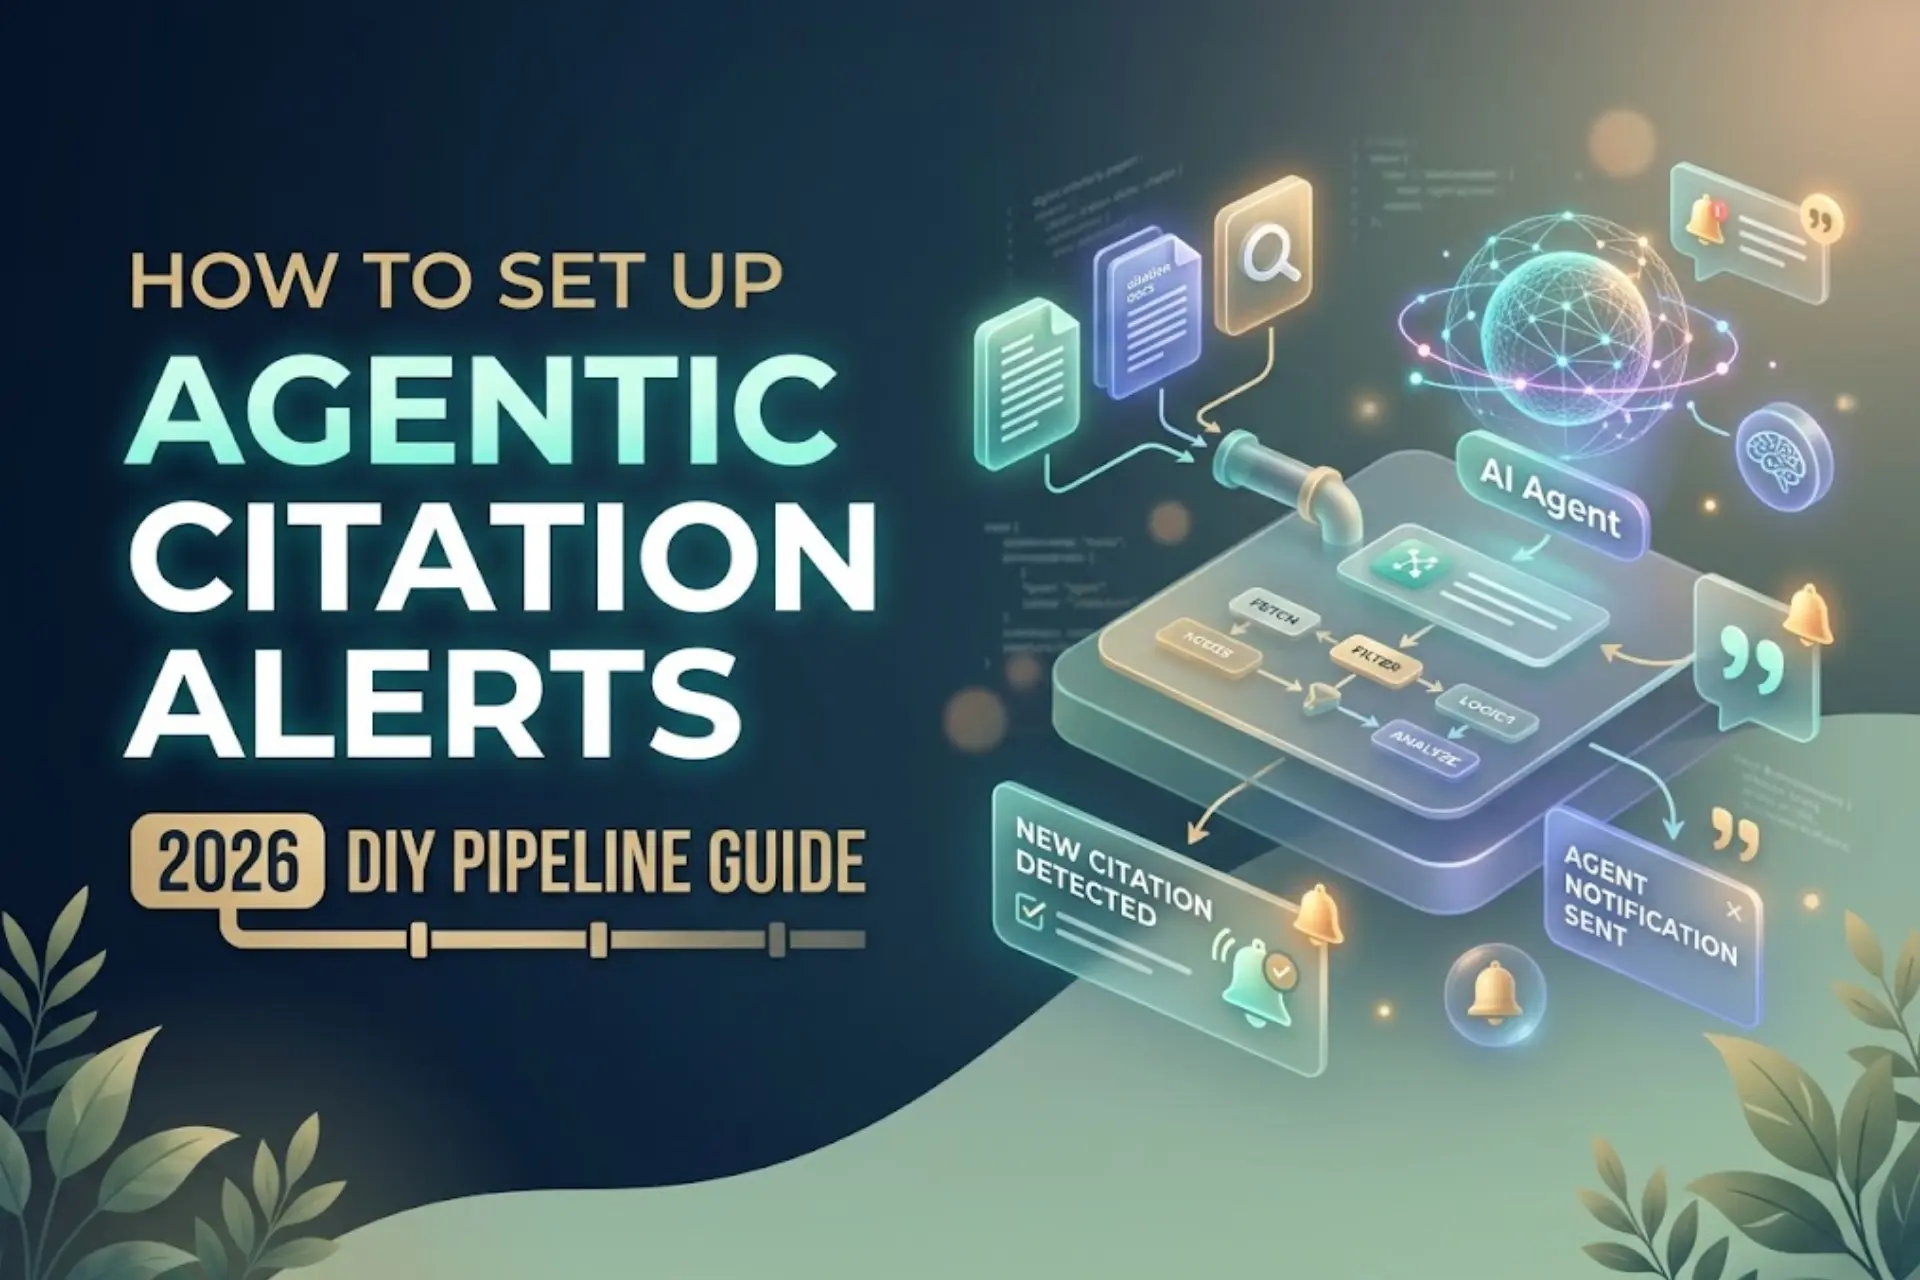
An alert pipeline is not a scraper with a bell on it. It is four small jobs chained together, each with a clean contract, so that a change in any one of them never silently breaks the others. The sweep asks the engines, the judge reads the answers, the delta store compares against a baseline, and the router decides who needs to hear about it.
The judge is where most homegrown setups go wrong, so it deserves precision. It is a language-model call with a structured-output contract: given one answer, it must return the cited domains, whether your brand is named, linked or merely implied, the sentiment of the mention, and a confidence score. Because the output is a fixed schema rather than prose, every downstream step — diffing, thresholding, trending — becomes simple data work instead of fragile text parsing.
| Stage | What runs | What it emits |
|---|---|---|
| Prompt set | Frozen list of buyer questions | Prompt manifest (versioned) |
| Engine sweep | Scheduled queries across engines | Raw answers + timestamps |
| Citation judge | LLM with structured output | cited_domains[], brand_status, confidence |
| Delta store | Diff vs rolling baseline | Gain/loss events per prompt × engine |
| Alert router | Severity rules + quiet suppression | Slack / email notifications |
Key Insight
Monitoring asks “where do we stand?” — alerting asks “what changed since the baseline?” That single diff step is the whole difference between a dashboard nobody opens and a notification your team acts on the same day.
For the workflow layer, an orchestration tool beats a cron script because you get retries, parallel branches and per-engine rate limits out of the box. We run these pipelines in n8n; the same shape works in Make or a small queue worker. If you want the dashboard-first variant of this stack, our citation monitoring build in n8n covers it in depth.
Set Up Agentic Citation Alerts in 5 Steps
The build below takes a first working version roughly a weekend, with most of that time spent on the prompt set rather than the wiring. Work through the steps in order — each one produces an artifact the next one consumes.
- Freeze your brand entity and prompt set. Write down the exact brand string and common misspellings, plus 3–5 competitors. Then collect 15–25 real buyer questions — the phrases a customer actually types — not marketing keywords. Mine them from sales calls, support tickets and audience research tools like SparkToro. Version this manifest; alert history is meaningless if the questions keep shifting under it.
- Build the scheduled sweep. Create one workflow branch per engine, each submitting the full prompt set and storing raw answers with timestamps, engine name and prompt ID. Run weekly by default; daily only for a handful of money prompts. Keep volume modest and prefer official APIs where an engine offers one — this is a monitoring pipeline, not a scraping operation.
- Add the citation judge. Route every stored answer through one structured-output LLM call returning cited domains, brand status (named / linked / implied / absent), sentiment and confidence. Require confidence ≥ 0.70 to accept a verdict; everything below goes to a review queue instead of the delta store. For a single-agent take on this judging layer, see our practitioner guide to Gemini agents for citation tracking.
- Diff against a rolling baseline. Store one row per prompt × engine × run: cited or not, and which domains. Compare each new run against a rolling 4-week baseline rather than last week alone. A citation lost on a money prompt, a competitor appearing where they were absent, or share moving more than your threshold — those are events; everything else is noise.
- Route alerts that deserve attention. Split notifications into three severities: red (lost citation on a money prompt), amber (competitor surge or share drop past threshold), green (new prompt detected, gained citation). Send red instantly to Slack, batch amber into a daily digest, and summarize green weekly. Suppress fully quiet runs — an “all clear” email every Monday trains people to ignore the channel.
Want this pipeline running without the build?
We ship agentic citation alert systems in days, not quarters.
Keep It Honest: False Positives and Thresholds
Language models are non-deterministic, and the same question can earn a different answer on Tuesday than it did on Monday. A naive setup that diffs single runs will cry wolf weekly, and a channel that cries wolf gets muted — which is worse than having no alerts at all. Honest thresholds are what keep the pipeline trusted.
Three rules handle most of the variance. First, never judge a single run: take the median of three sweeps before writing a gain or loss event. Second, diff against a rolling four-week baseline so one quirky week cannot manufacture a trend. Third, alert on slope, not level — a citation share that slides from 34% to 31% to 27% over three weeks is the real story, even if no single week looked dramatic. Industry coverage of AI search growth keeps reminding teams that the engines themselves are moving targets (see Search Engine Journal).
Key Point
Start with exactly two triggers: a lost citation on a money prompt (red) and a ±5-point share move against the rolling baseline (amber). Resist adding more for the first month — every extra rule multiplies the false-positive surface.
Not every team wants to own a pipeline, and that is a legitimate choice. Commercial AI-visibility platforms such as peec.ai handle the sweep for you; the tradeoff is fixed prompt taxonomies and less control over the judge. The build-versus-buy line is simple: if your prompt set is standard and your team is small, buy; if your questions are proprietary or your competitors unusual, build.
What to Do When an Alert Fires
An alert is not a to-do item; it is a hypothesis that something moved. The response playbook below keeps the first hour calm: verify the event is real, diagnose why it happened, then decide whether content, PR or product owns the fix. Skipping the verify step is how teams end up rewriting pages because of one non-deterministic Tuesday answer.
| Alert | First check | Then act |
|---|---|---|
| Lost citation — money prompt (red) | Re-run manually 3× in a clean session | If real: update the page the engine used to cite, refresh its evidence |
| Competitor surge (amber) | Diff their newly cited URL against yours | Close the content gap: depth, data, freshness, entity clarity |
| New prompt detected (green) | Confirm it is a real buyer question | Publish the direct answer; add it to the frozen manifest |
Red alerts deserve a named owner and a same-day response SLA, because a money answer that stops citing you is quietly re-routing revenue. Amber alerts batch into a weekly review where patterns matter more than single events. Green alerts feed the content backlog — our guide to updating high-citation sources covers the edit playbook.
Response Checklist
- Verify — re-run the prompt three times in a clean session before believing the alert
- Diagnose — pull the engine’s current answer and identify which sources it cites now
- Decide — assign the fix to content, PR or product within 24 hours
- Ship — make the smallest evidence-bearing update that answers the prompt better
- Log — record the event and outcome so the threshold can be tuned next month
“A citation you lost today is a buyer you lose quietly for weeks — alerting turns that silent drift into a same-day decision.”
— Agentic monitoring design principle
Conclusion: Stop Checking, Start Getting Told
Agentic citation alerts replace anxious manual checks with a pipeline that sweats the details for you: a frozen prompt set, a scheduled sweep, a structured judge, a baseline diff and a router that only speaks up when something moved. The build is a weekend, the discipline is in the thresholds, and the payoff is knowing about a citation shift the day it happens instead of the month after.
Start small — one engine, ten money prompts, two triggers — and let the alert history earn your team’s trust before you scale it. If you want a second pair of eyes on the setup or a done-with-you rollout, contact us and we will review your prompt set in one session.
Frequently Asked Questions
What are agentic citation alerts in simple terms?
They are automated watchers for AI answers. On a schedule, an agent asks ChatGPT, Perplexity, Gemini and Google AI Overviews your buyer questions, checks whether each answer cites your brand, and sends you a notification only when that citation footprint changes — a gain, a loss, or a competitor appearing.
Which AI engines can I monitor this way?
The four that carry most commercial traffic today — ChatGPT, Perplexity, Gemini and Google AI Overviews — plus Microsoft Copilot as a fifth. Prefer official APIs where an engine offers one, keep query volume modest, and treat engine terms of service as a design constraint, not an afterthought.
Do I need to write code to set this up?
No — a visual workflow tool like n8n plus one structured-output prompt covers the whole pipeline: scheduling, parallel engine branches, the judge call, the diff and the Slack/email routing. The only “engineering” is designing the prompt manifest and the thresholds, which this guide walks through.
How often should the sweep run?
Weekly is the standard cadence, with a daily mini-sweep for the handful of money prompts that drive decisions. More frequency mostly buys more variance, not more signal — and remember the verdicts are median-of-three, so each “data point” already averages out engine randomness.
How is this different from rank tracking?
Rank tracking watches your position in a list of links; citation alerting watches whether you appear inside a generated answer at all. There is no position 4 in a chat reply — the engines synthesize an answer and cite a handful of sources. The metric becomes share of answer, not rank, and the drift it detects is invisible to classic trackers.
What does it cost to run a pipeline like this?
The moving parts are modest: workflow tooling (n8n self-hosted or a small cloud plan), LLM tokens for the judge pass over each answer, and an alert channel you already own. For a 25-prompt set across four engines on a weekly cadence, the judge pass is measured in low thousands of calls a month — a few dollars of tokens (illustrative estimate), not a line item.
Is your brand invisible in AI answers?
Get a 15-point AI visibility review and see exactly which engines cite you today — and which cite your competitors instead.
Want to watch a citation alert fire in real time?
We’ll run your own prompt set through the pipeline live and show you the alert, the diff and the verdicts in a 20-minute session.
Leave a Reply